✦ The unstructured companion to DataQualify
Turn every document into AI-ready data.
PDFs, contracts, emails, spreadsheets — 80% of enterprise knowledge is unstructured. DataQualify Unstructured parses, scores, governs and prepares it all, so your models and agents can finally trust it.
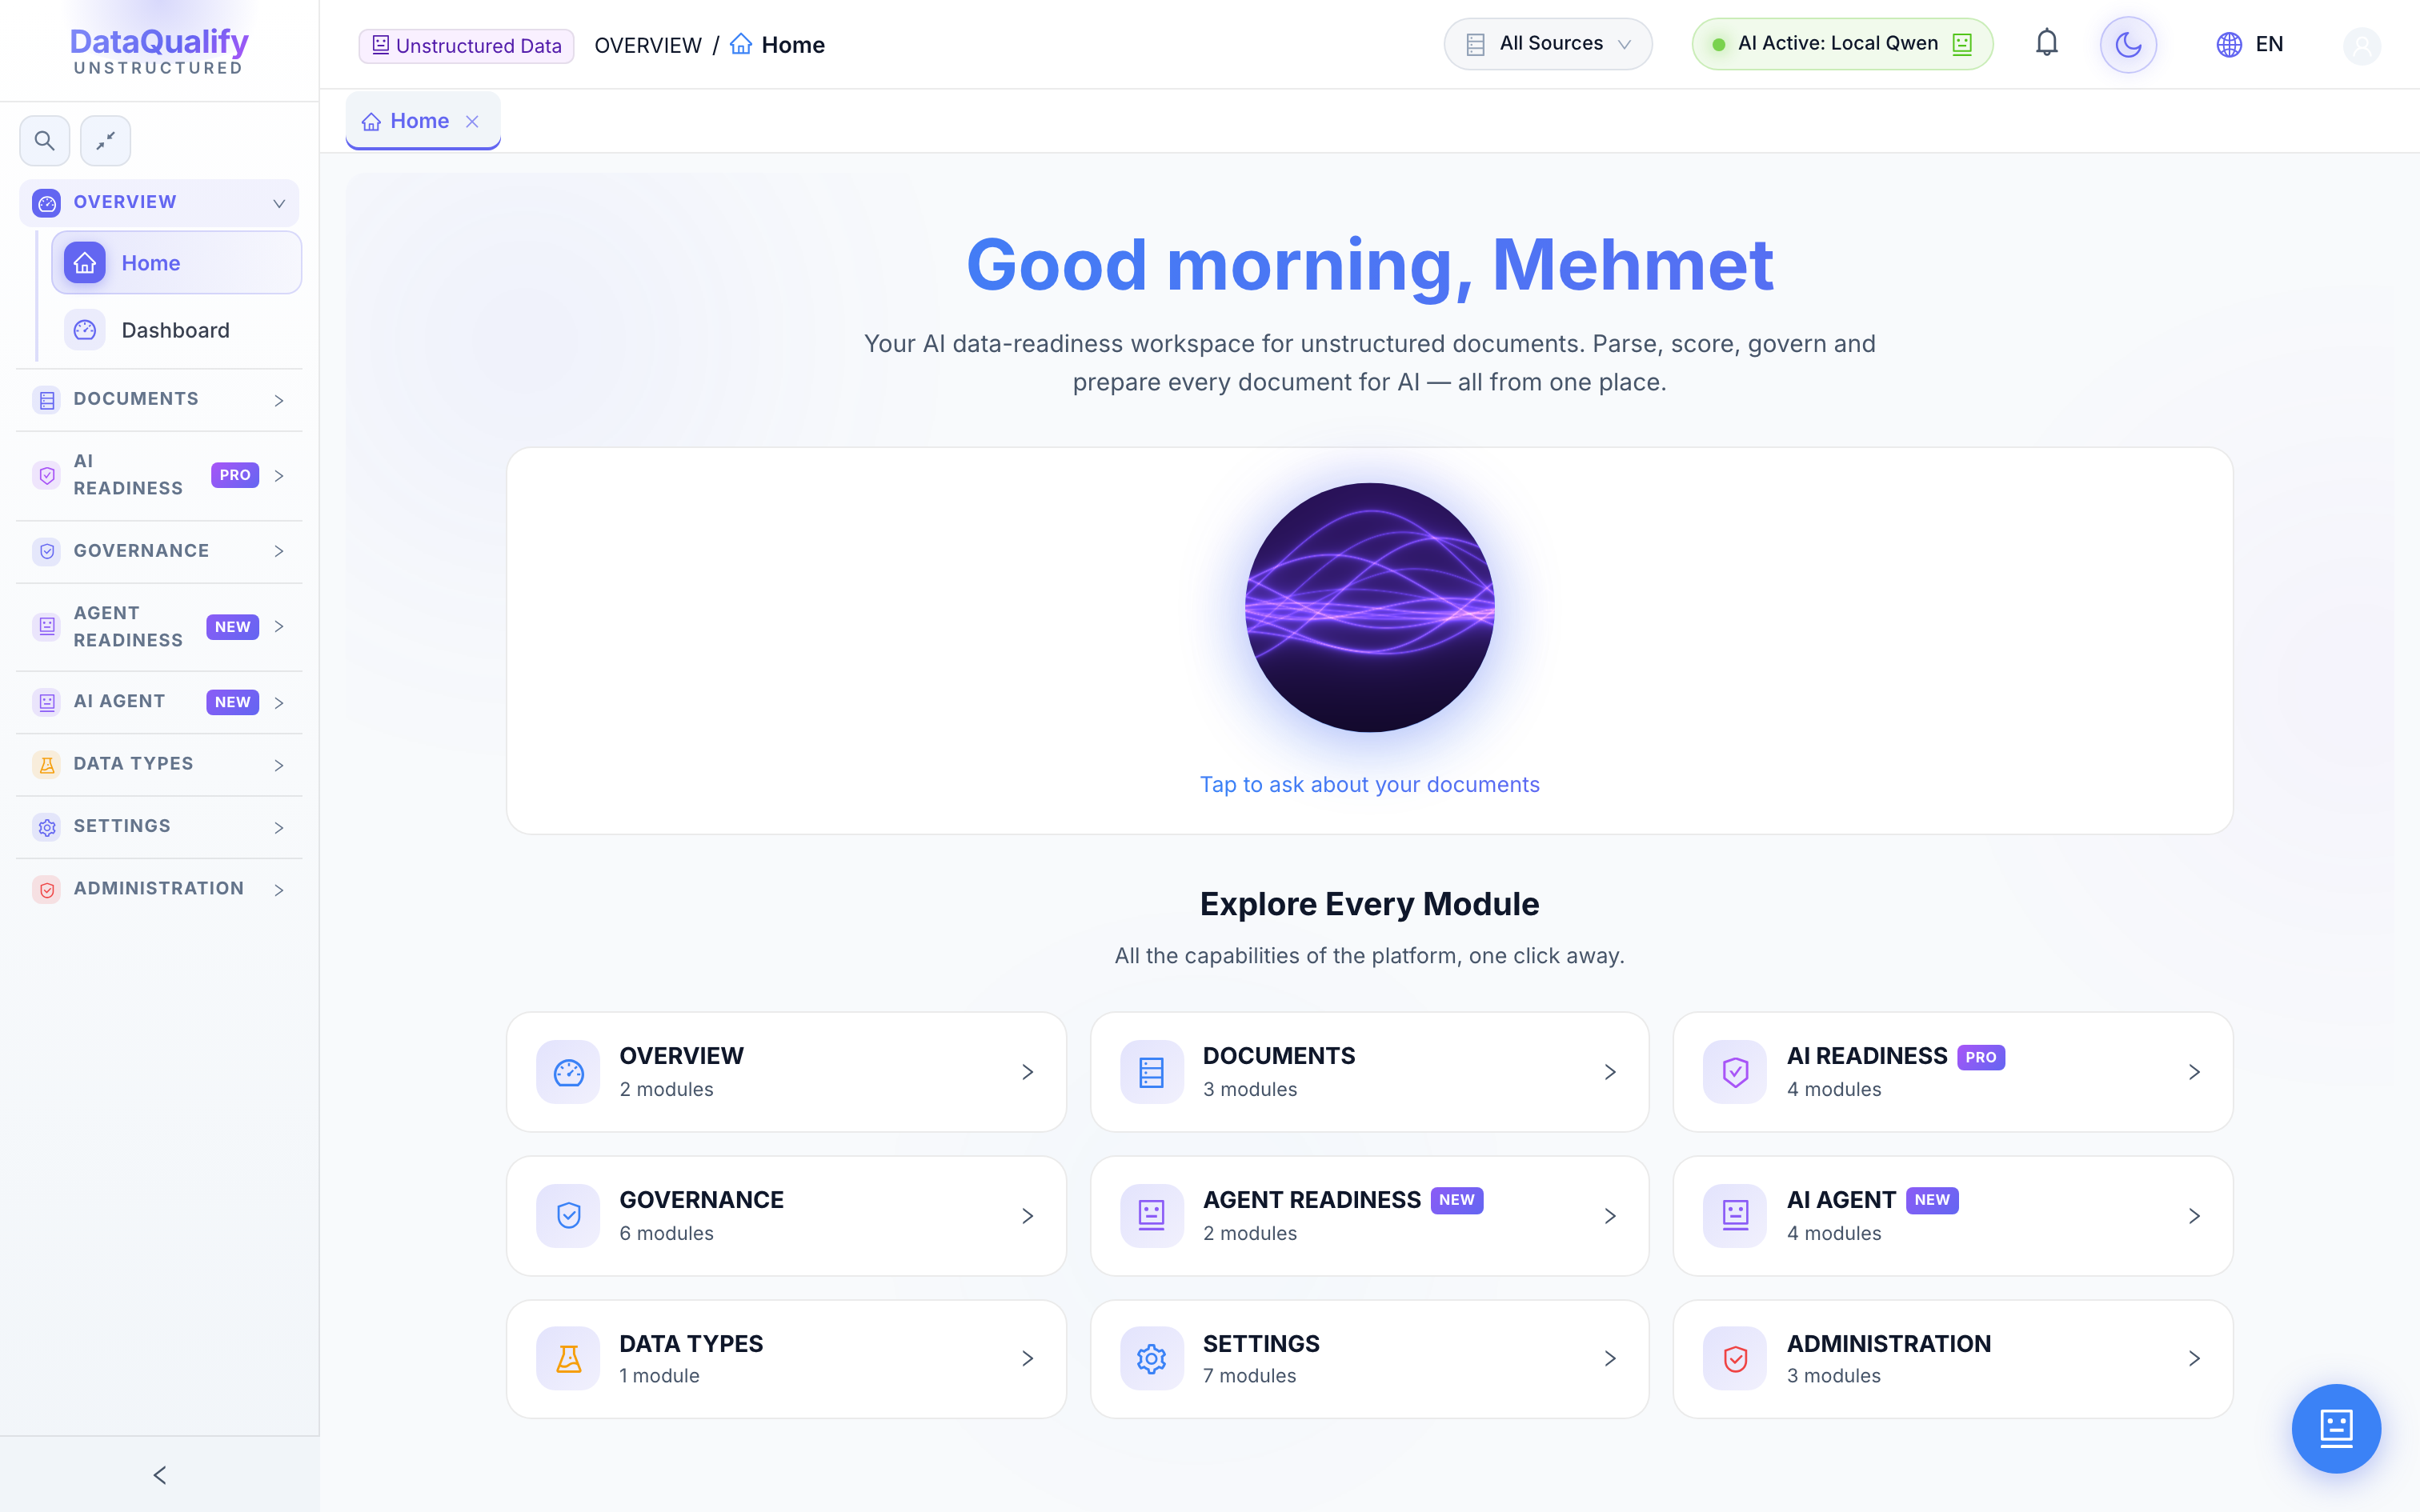
Platform
Everything unstructured data needs to become AI-ready.
One platform covers the whole journey — from raw file to governed, agent-ready knowledge.
Smart Parsing
PDF, DOCX, PPTX, XLSX, Markdown, scans — extracted with high fidelity, tables and structure intact.
AI-Readiness Scoring
Every document scored on parsability, completeness, consistency, freshness, clarity, structure and metadata.
Semantic Chunking
Chunk, embed and inspect the semantic structure of each document for reliable retrieval.
Ambiguity Detection
Surfaces contradictions, stale content and conflicting statements before they poison your models.
Document Lineage
Visualize versions, relationships and derivation across your entire corpus.
Governance & Catalog
Ownership, classification and metadata coverage — a governed catalog for every file.
RAG Playground
Query your corpus with retrieval-augmented generation and inspect answers and sources.
Autonomous Agents
Compose multi-step agent pipelines that parse, score and remediate documents on their own.
See it in action
Real screens, real documents.
Screenshots straight from the product — not mockups.
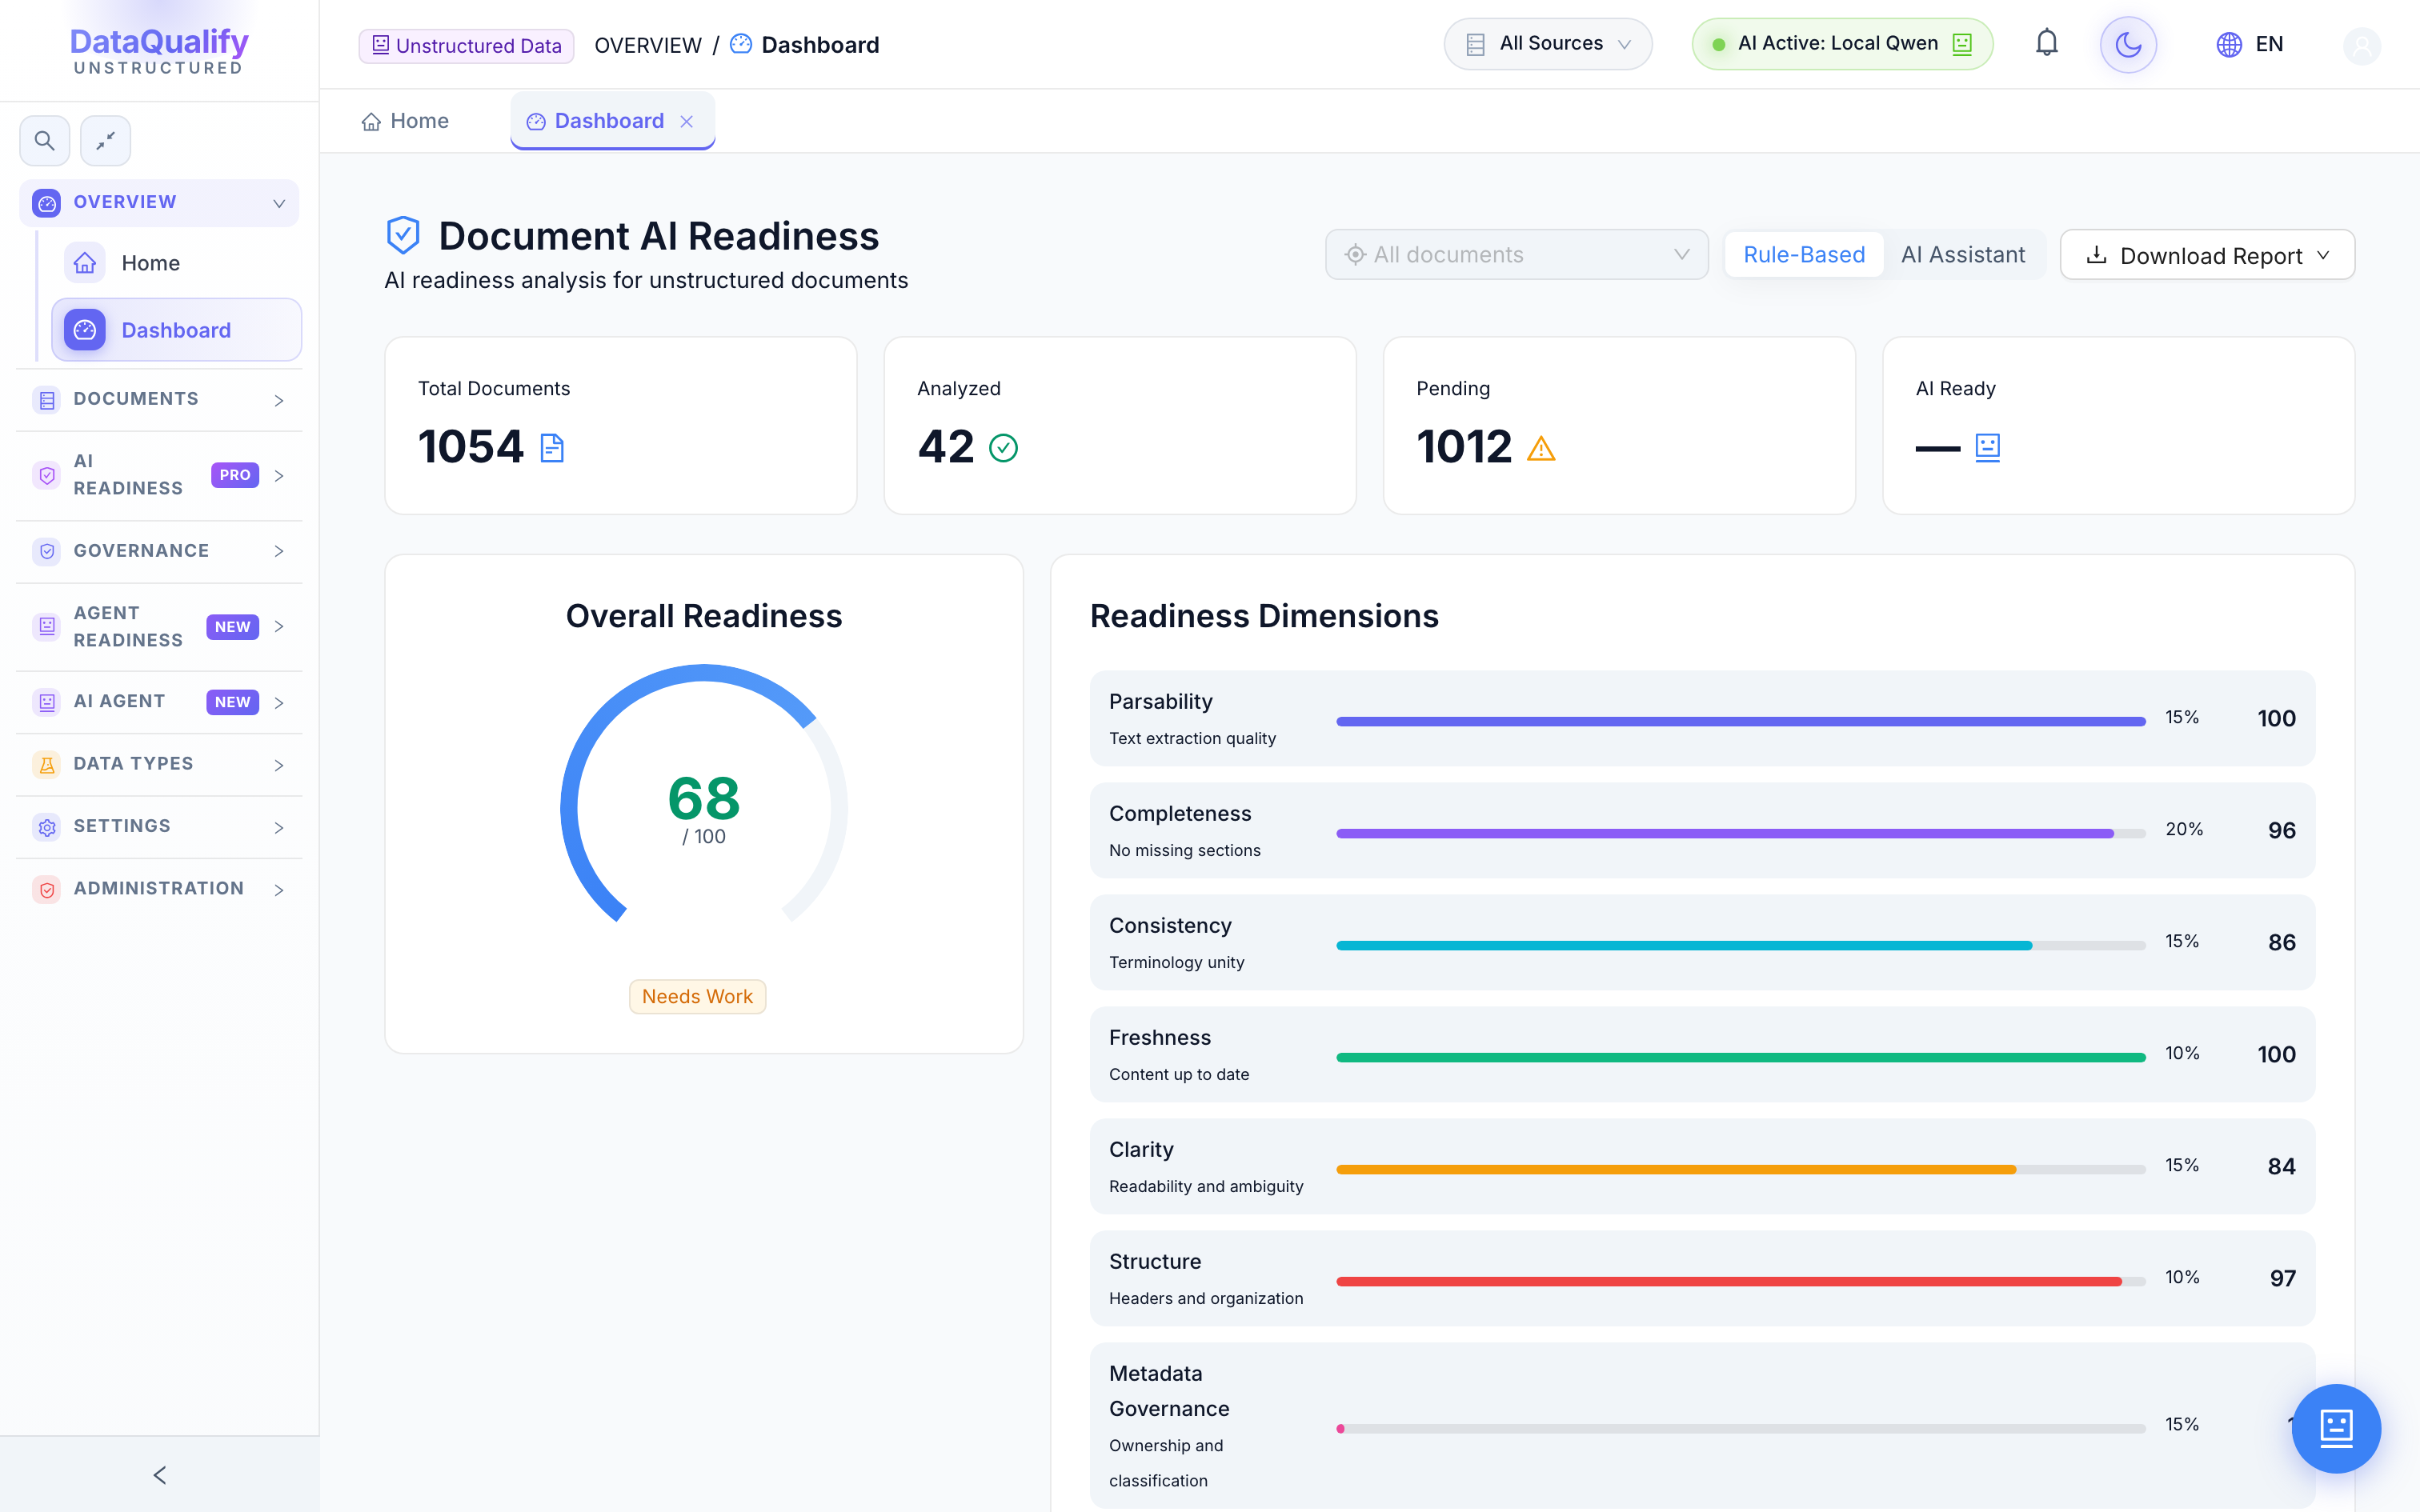
Executive scorecard of AI-readiness across your whole corpus.
Module suites
Nine suites, one platform.
Thirty-plus modules, organized into the way teams actually work.
How it works
From raw file to agent-ready knowledge.
01
Connect sources
Point Unstructured at your DMS, folders or mailboxes and sync every document.
02
Parse & analyze
Files are parsed, chunked and scored for AI-readiness automatically.
03
Govern & remediate
Catalog, classify and fix ambiguity, staleness and structure issues.
04
Feed agents & RAG
Serve clean, governed knowledge to your RAG apps and autonomous agents.
Integrations
Your sources, your LLMs.
Connect enterprise document sources and run any LLM — cloud or fully local.
Don't see yours? Connect any S3-compatible store or OpenAI-compatible endpoint. Talk to us →
30+
modules
across nine suites
7
readiness dimensions
scored per document
100%
local option
air-gapped LLMs
4
languages
EN · TR · ES · DE
Who it's for
Built for the people who own the documents.
Chief Data Officer
A single readiness score to prove the corpus is fit for AI.
Data Engineer
Automated parsing and chunking pipelines instead of glue scripts.
Governance Lead
Ownership, classification and audit across every document.
AI / ML Team
Clean, governed context so RAG and agents stop hallucinating.
Compliance
Full audit trail and access control on sensitive content.
Analyst
Search and question the whole corpus in plain language.
Outcomes
Why teams adopt it.
AI projects ship faster
Stop cleaning documents by hand — readiness scoring and remediation are automated.
Agents you can trust
Only governed, unambiguous knowledge reaches your models and agents.
Nothing leaves your walls
Run every parser and LLM locally — sensitive documents never leave the building.
Security & deployment
Enterprise-grade, air-gap ready.
Deploy in the cloud, hybrid, or fully local — the choice is yours.
RBAC
Role and permission matrix with request-and-approve access.
Encryption
Secrets and credentials encrypted at rest with Fernet.
Zero egress
Local LLM option keeps every document inside your network.
Audit trail
Every action logged and traceable across the platform.
FAQ
Questions, answered.
Does my data ever leave my network?⌄
No — you can run every parser and LLM fully locally (Ollama, LM Studio, local Qwen). Nothing has to leave your walls.
How is this different from DataQualify?⌄
DataQualify handles structured, tabular data quality. DataQualify Unstructured is its companion for documents — the same platform family, different data shape.
Which document types are supported?⌄
PDF, DOCX, PPTX, XLSX, Markdown, images and scans, including complex tables and mixed-type files.
Which LLMs can I use?⌄
Ollama, OpenAI, Gemini, OpenRouter, LM Studio and local models like Qwen — swap providers per task.
Can agents act on documents automatically?⌄
Yes — the AI Agent suite lets you build multi-step pipelines that parse, score and remediate on their own.
What languages does the UI support?⌄
English, Turkish, Spanish and German, switchable at any time.
📅 Book a demo
Make your documents AI-ready.
A live demo with your own documents — see readiness scoring, governance and agents on your real corpus.